Why Raw HTML Breaks LLM Reasoning and What Clean Extraction Actually Fixes
Stripping page noise before inference keeps the model's reasoning on content.
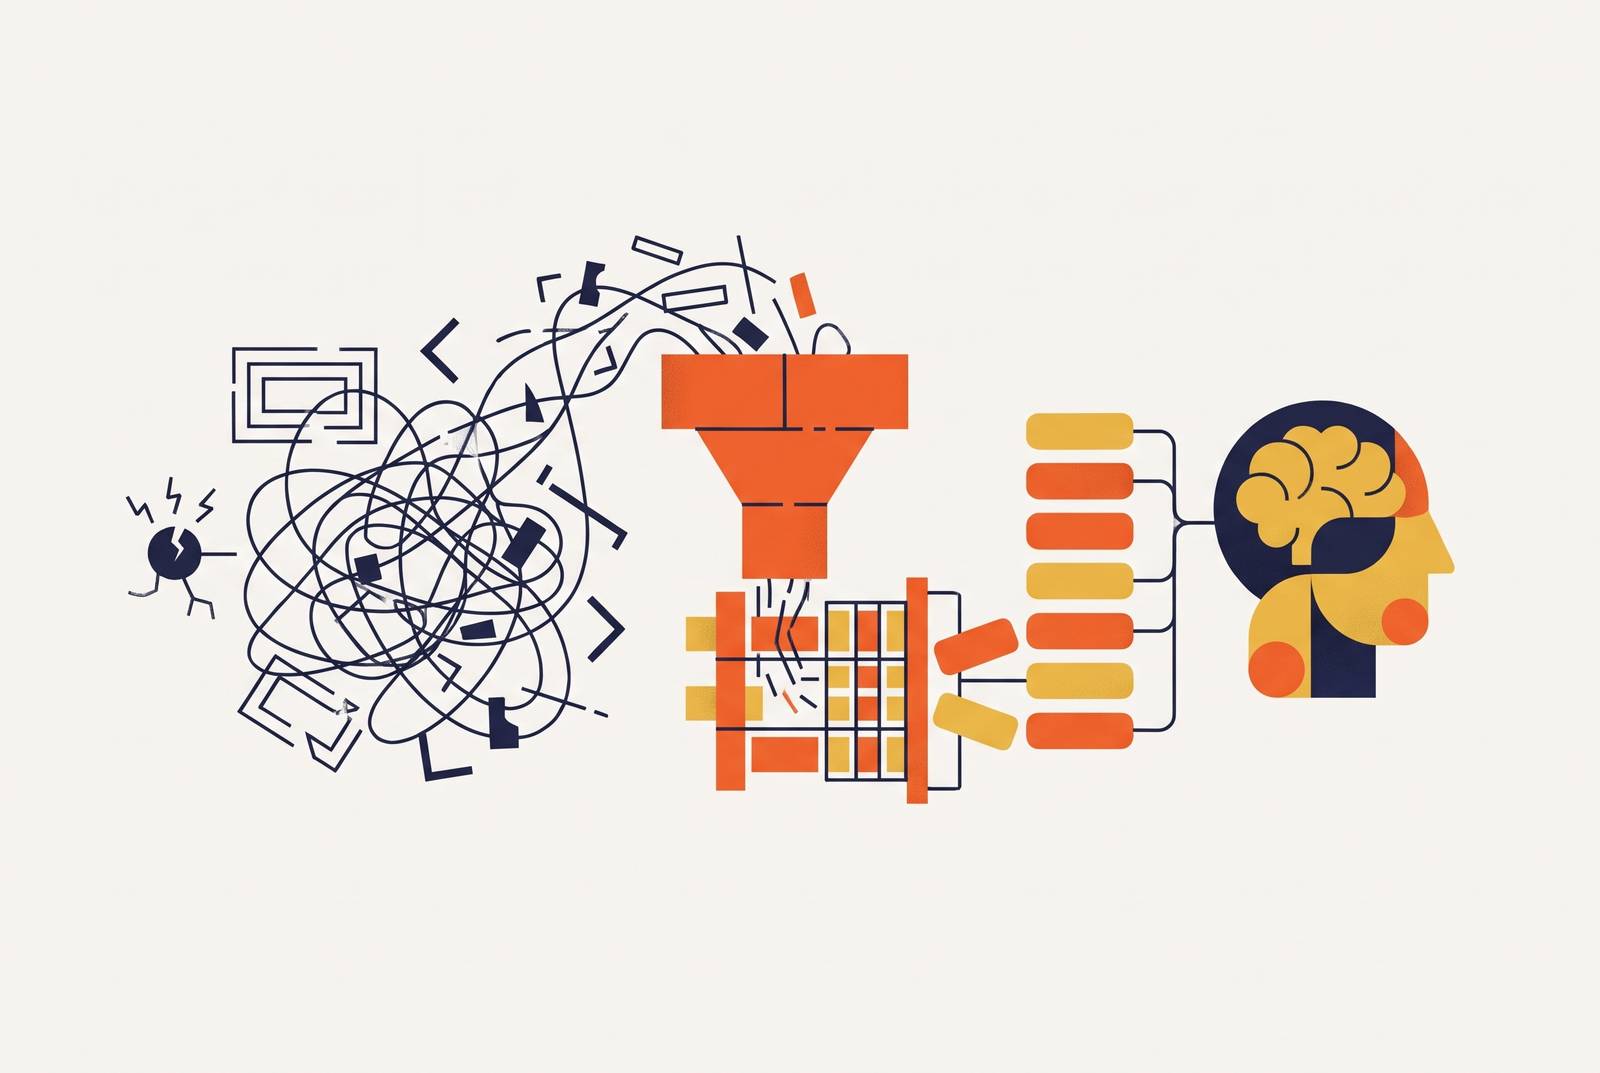
LLM-ready structured data extraction from web pages means removing page machinery before passing the content to the model, then delivering it as Markdown or structured JSON with meaningful relationships intact. Raw HTML weakens reasoning through a compounding signal-to-noise problem. Clean extraction fixes the input so that the model spends its finite reasoning budget on the content the task requires.
Why the context window is a reasoning budget, not just a size limit
A context window is a budget. Every token that goes in uses some of the model’s capacity to connect information and give an accurate answer. Content that helps with the task is worth that cost. Material that has nothing to do with the task spends from the same account without helping the model answer the question. The constraint applies to every production deployment.
A larger window gives the model more room. It does not make irrelevant input free. The model still has to distribute attention across what it receives, and attention is not uniform. Tokens are weighted relative to one another, so a large volume of unrelated material can distort which parts of the input appear important.
A document can fit inside the advertised window and still be a poor use of it. The share of input that deserves the model’s attention matters alongside its ability to accept that input. For web content, irrelevant input consumes capacity before the model sees the first sentence of the article.
What raw HTML actually contains when a real page is fetched
A fetched page contains much more than its authored text. Navigation menus, breadcrumb trails, headers, footers, cookie consent banners, and sidebar widgets arrive with their full markup. These elements help operate a website, but they are usually not the information a reader came for. The model receives the furniture with the document. Nothing about fetching a page automatically separates the two.
The payload also includes inline CSS and style attributes, often repeated across dozens of elements. JavaScript bundles sit in script tags, while event handler attributes and tracking elements add material that has nothing to do with the requested content. Class names, data attributes, and framework-generated IDs contribute more tokens without necessarily explaining the page’s subject.
Duplication adds another layer to the file. The same navigation may appear in a mobile menu, a sticky header, and a footer. Related-article links can recur in multiple widgets, while a call-to-action block returns after successive sections like a salesperson who has forgotten the conversation ended. Each instance is part of the raw payload, even when its message is identical. On a typical modern page, the authored sentences, headings, and data can therefore occupy only a small fraction of the total token count.
How boilerplate, markup, and navigation compound into a signal-to-noise failure
The damage compounds. Structural markup reduces the density of useful text, while repeated navigation gives irrelevant words disproportionate representation. Scripts and style blocks compete for attention with the content that is left. Removing just one category can leave the others crowding the same signal.
Navigation links, button labels, and footer copy are fluent English. A model must tell those words apart from the page’s actual argument instead of assuming that text belongs in the answer just because it is readable. Repetition complicates that distinction further. A site-wide label appearing at both ends of a page may receive more representation than a crucial claim stated once in the body.
Code introduces a different kind of distraction. Scripts and style blocks can superficially resemble structured data or logic, even when they contain nothing useful for the requested summary or extraction. Meanwhile, nesting surrounds content with structural tokens. A single sentence may sit inside five or six nested div elements, with opening and closing tags around it. That depth describes containment in the page.
Together, these effects can make a substantial page less useful to a model than a shorter, cleaner one. The shorter page has fewer facts but a higher signal density. Good content is not enough by itself. When the surrounding noise consumes and distorts the available attention, the model has less useful capacity for reasoning over that content.
Where LLM outputs visibly break down when fed raw HTML
In a pipeline, this failure often looks like weak model performance. A summary sounds right but gets some of its content from navigation text, ad copy, or repeated link labels. The response may remain fluent throughout. That fluency makes the error harder to spot, because the model has assembled readable language from the wrong parts of the page.
Fact extraction can fail more quietly. A key date, figure, or claim buried in the body is omitted while earlier navigation and script blocks dominate the input. Structural confusion produces a related error, where a returned value belongs to a sidebar or recommended-content block. A product’s price or a person’s title may be the requested field, yet the model selects information from the wrong page region. The output has the right shape and the wrong source.
The model cannot use content outside the context window, and it may give too little attention to content that fits because of the noise around it. These are different failures with a similar consequence. The answer lacks information that was present somewhere in the fetched document.
Repeated runs can expose another symptom. The same noisy page can yield meaningfully different extractions as irrelevant tokens pull the output toward competing interpretations. Input quality can therefore contribute to instability that a developer might otherwise blame on temperature alone. Clean extraction addresses reliability as well as readability.
How do you get web page content into a format an LLM can use?
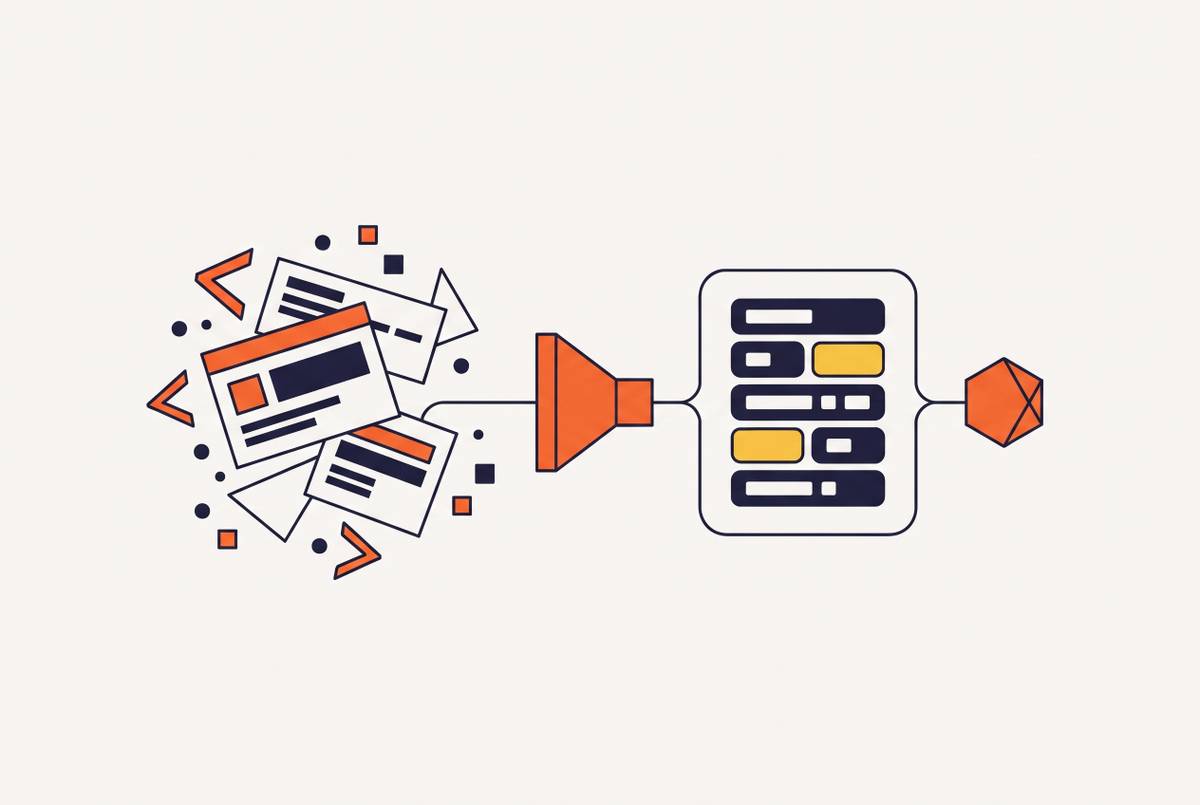
Clean extraction transforms the token stream before inference begins. It removes navigation, page headers and footers, sidebars, and repeated template blocks upstream, rather than asking the model to ignore them after they have consumed context. It also removes scripts, style attributes, tracking elements, and structural tags that are not needed. The distinction is where the work happens. Parsing removes the distractions before the reasoning budget is spent.
The retained material includes headings, body text, tables, lists, and meaningful metadata. In Markdown or structured JSON, heading levels preserve hierarchy, list structures preserve grouping, and table relationships keep values connected to their context. Clean does not mean flattened. Stripping out all the structure would throw away information the model needs.
Deduplication handles the repetition that ordinary tag removal can leave behind. A call to action still repeats the same text after its markup is gone. Removing duplicate blocks at extraction time prevents them from continuing to skew the input. This is why converting syntax alone is not the same as extracting content. Both selection and structure have to survive the transformation.
The resulting document’s length more closely reflects how much information the page contains. A long article produces a long extraction, while a thin page produces a short one. Genuine content can still exceed a context window. The improvement is that template complexity no longer decides how much room remains for the article, table, or description the model was asked to process.
Why output format choice — Markdown, HTML, JSON — changes what the model can do with the content
Markdown works well for tasks where the model needs to follow a document’s argument. It preserves headings, emphasis, and lists while remaining readable as plain text, making it useful for summarization, question answering, and retrieval. The structure is visible without much surrounding machinery. Sending raw HTML when Markdown would suffice is like supplying a floor plan when someone asked for the address.
Structured JSON works well for tasks that need fields whose contents are clearly named. Separating title, body, author, date, and tables as arrays tells the model what kind of information belongs where. That distinction reduces ambiguity when the required output must populate a schema. Markdown presents a document to follow, while JSON presents fields to distinguish. Neither is the best choice for every task.
Cleaned HTML has a narrower role in this comparison. Semantic elements can be useful when the task explicitly needs link targets or image references, but their tags still consume tokens. Format selection is another budget decision.
How clean extraction changes the economics of running LLMs over web content at scale
Most major providers price inference per token, so a raw-HTML pipeline pays to submit navigation, markup, and scripts whether or not they help produce an answer. That cost repeats with every page. A template that looks harmless in one request becomes a regular item on the bill across a large workload.
Longer inputs also increase per-call latency. At high request volumes, the accumulated delay can constrain pipeline throughput rather than remain a minor wait on an individual response. Cleaner input reduces the amount of material presented for inference. This cuts both the length of the document on screen and the amount of needless input sent through a costly stage of processing.
Downstream systems need usable structured data, so incorrect or inconsistent results require retry logic, validation layers, and sometimes human review. The cost does not stop at the first answer. Noisy input can cause more work later in the pipeline even when the first model call succeeds.
Upstream extraction moves noise removal from inference to cheaper parsing compute. A web data API returning clean Markdown or structured JSON can therefore save a developer some cleanup and serve an infrastructure role. Its value depends on whether the returned content removes boilerplate, preserves useful relationships, and fits the downstream task. Those qualities shape both inference spending and the work required to handle the results.
What to audit when an LLM pipeline produces inconsistent or poor outputs from web content
The first step is to check what is in the input before changing the model, prompt, or temperature. Inspect what actually reaches the model and measure the shares of tokens devoted to markup, navigation, scripts, repeated template blocks, and authored content. If much of the input is noise, its quality is worth testing first. The fetched page is not the finished input. Treating the two as interchangeable can hide the source of poor results.
Next, compare the same content as raw HTML and clean Markdown while holding the other variables constant. Look for improvements in both answer quality and consistency. This comparison tests the signal-to-noise diagnosis directly instead of changing several parts of the pipeline and guessing which helped. It also grounds the decision in the content the pipeline actually handles.
Then check whether the information of interest reaches the model intact. Follow the article body, data table, or product description through the input, and look for earlier noise pushing it toward or beyond the usable window. A missing passage and an overlooked passage can look alike in the answer but require different interpretations of the input.
After that, compare repeated runs on identical inputs. High variance is a reason to investigate competing noise. Finally, estimate raw HTML’s token overhead across a representative sample of pages. This turns the diagnosis into a production decision. At scale, the case for extraction rests on how much irrelevant input it removes and how much downstream correction that cleaner input can avoid.