Extracting Company Technographic Data From Public Web Sources
Job postings reveal the backend systems that website code alone can never expose.
A company's technology stack is front-end website code, backend databases, internal SaaS tools, and cloud infrastructure, stacked on top of each other like a layer cake nobody invited you to eat. A web crawler can read what a website exposes: script tags, tracking pixels, CSS frameworks, DNS records. That's the equivalent of judging someone's whole diet by looking at what's on the kitchen counter. The backend systems, internal CRMs, and data warehouses doing the real work stay in the pantry, out of view, with no public front-end fingerprint to show for it.
Job postings fill part of that gap. When a company lists a role requiring "experience with Snowflake and dbt," that's strong public evidence those tools are in active use, even though neither will ever appear in the corporate site's source code. Crustdata's own numbers back this up directly: among 133 teams that came to Crustdata asking for technographic data, the most common request wasn't a website crawl at all. It was inferring the stack from job postings, because backend and internal systems are visible there, in requirements and tooling sections, not in page source.
That buyer preference is the whole argument in miniature. Treating web-crawl data and job-posting inference as substitutes and picking one produces a dataset that has a shape, just not the company's actual shape. Treating them as complements gets the picture a lot closer to whole. The rest of this piece is organized around that one structural fact: each collection method covers ground the other can't reach, and the gap between them is exactly where the valuable systems tend to live.
What web-crawl detection sees
HTML fingerprinting, along with DNS and header analysis, is genuinely strong at one job: spotting front-end and infrastructure technology. Analytics tags, tag managers, chat widgets, CDN providers, CMS platforms, and ecommerce frameworks all leave readable traces in page source and in DNS records, and a crawler built to look for those traces finds them reliably. Mechanically, this works by parsing several channels at once: script tags, CSS imports, inline code patterns, HTTP response headers, and DNS records. Those channels together map the publicly visible stack with real accuracy.
The ceiling on that accuracy is hard and it doesn't move. Backend databases, data warehouses, internal SaaS platforms, and most of the business software a company actually runs on are invisible to a crawler, simply because none of it is referenced anywhere in public page code. A crawl can't detect what a page never mentions, the same way a photo of someone's front door tells you nothing about the floor plan.
The downstream consequence matters for anyone building or buying this data. A crawl-only technographic dataset will nail the analytics vendor, the chat provider, the CMS. It will systematically under-report the exact systems that sales and go-to-market teams most want visibility into: the CRM, the data warehouse, the internal platforms that actually drive how a company operates. A large share of modern sites render their content client-side, and a crawler that doesn't execute JavaScript the way a browser would simply won't see that content at all. That detail becomes more important later, when the pipeline itself is on the table.
How job-posting inference reaches the internal stack crawlers cannot touch
Job postings are a different kind of public record than a webpage, and they carry information a crawler will never see. When a company advertises for an engineer who knows Snowflake, dbt, Kubernetes, or a specific CRM, it is publicly announcing stack choices that will never appear in a script tag. Nobody writes "Kubernetes" into their homepage footer. They write it into a job requisition, because that's where they're trying to reach the people who already know how to use it.
The method behind this is straightforward: read job descriptions, careers pages, engineering blogs, and public repositories, and extract named technology mentions from them. They're specific tools a company is actively staffing around, named in plain text by the company itself. The signal runs especially strong for backend infrastructure, data platforms, and internal tooling, precisely because those are the categories where specialized hiring produces the most specific public evidence of what a company runs day to day.
Crustdata applies language processing to job postings pulled from more than 15 sources, including career pages, job boards, and applicant tracking systems, and tracks coverage across tens of thousands of technologies. Coresignal takes a similar approach from a different angle, delivering structured public web data that includes job posting records, with new records added every six hours and a large volume refreshing each month. That cadence says something important on its own: recency is treated as a design goal here, not an afterthought, because a job-signal source that only updates once a quarter is already out of date by the time anyone uses it.
None of that makes job-posting inference a complete picture by itself. The honest limitation is that inference is probabilistic. A posting signals intent and current tooling, but it doesn't confirm that a tool is running in production or deployed company-wide. Sometimes a company posts for a tool it's still evaluating, not one it has fully committed to. That's a real gap, and it's exactly the kind of gap the next signal type exists to narrow.
Why combining signal types produces a more complete picture
Web-crawl data and job-posting inference, lined up side by side, barely overlap in coverage. Crawl data is strong wherever the stack is front-end-visible. Job-posting inference is strong wherever the stack is internal and backend. A pipeline running both at once catches what neither one catches alone, and that's not a theoretical benefit, it's the literal reason buyers keep asking for both.
This isn't an isolated opinion. A research platform operator working with Crustdata's team described stitching together several tools at once, pulling from BuiltWith, Coresignal, and a handful of web and news sources, as the working standard for research-grade technographic data. ZoomInfo runs the same logic at platform scale, blending crawling across more than 20 source types with verified and licensed data. No single channel there is trusted to carry the whole dataset on its own.
Combining signals also fights decay. Tech stacks don't sit still: companies adopt new tools and retire old ones constantly, and a pipeline that only re-crawls or only re-reads postings on its own schedule will miss changes the other signal would have caught sooner. The two signals don't even decay at the same speed. A front-end change appears in a crawl within days of a site update. Job-posting inference lags behind, sometimes by weeks or months, because it depends on a company actually posting a role after it adopts a tool. Knowing which signal leads and which trails is part of using both correctly, not a detail to shrug off.
The practical implication for anyone actually building a pipeline is blunt: wire both signal types together from the start, because retrofitting a second one onto a system built for just one is a much bigger job than building for both from day one.
How the extraction layer has changed
Extraction is built differently now than it used to be, in a way worth understanding before anyone starts sketching a pipeline. Traditional scraping relies on CSS selectors, XPath, and regular expressions. Those are fast and cheap per page, but brittle. A site redesign breaks the selector overnight, and the maintenance overhead compounds as the number of target sites grows.
Large language models offer an alternative: point a model at a page and let it extract the relevant fields without a hand-written selector. That flexibility comes at a cost, since per-page inference is slower and more expensive than a pure selector hitting a cached pattern. For a pipeline running high volume on a tight budget, selectors still win on raw economics.
A third pattern has emerged that tries to take the best of both. Instead of paying the inference cost on every single page, an agent analyzes a target site's structure once, then generates extraction code based on that analysis. That generated code then runs at machine speed across every subsequent page, with no further inference overhead. It's a hybrid built to capture the adaptability of an AI model and the scale economics of a plain script, and it's become the practical answer to a real trade-off rather than a trend adopted for its own sake.
JavaScript rendering is one unglamorous but essential requirement that makes the rest of this possible. A large share of the sites that make up the modern web render their content client-side, and without headless browser execution, a crawler gets back empty or incomplete HTML from exactly those sites. It's a precondition for accuracy, full stop, because a crawler that can't render JavaScript is effectively blind to a large and growing portion of the technology landscape in 2026.
Stages of a Technographic Extraction Pipeline
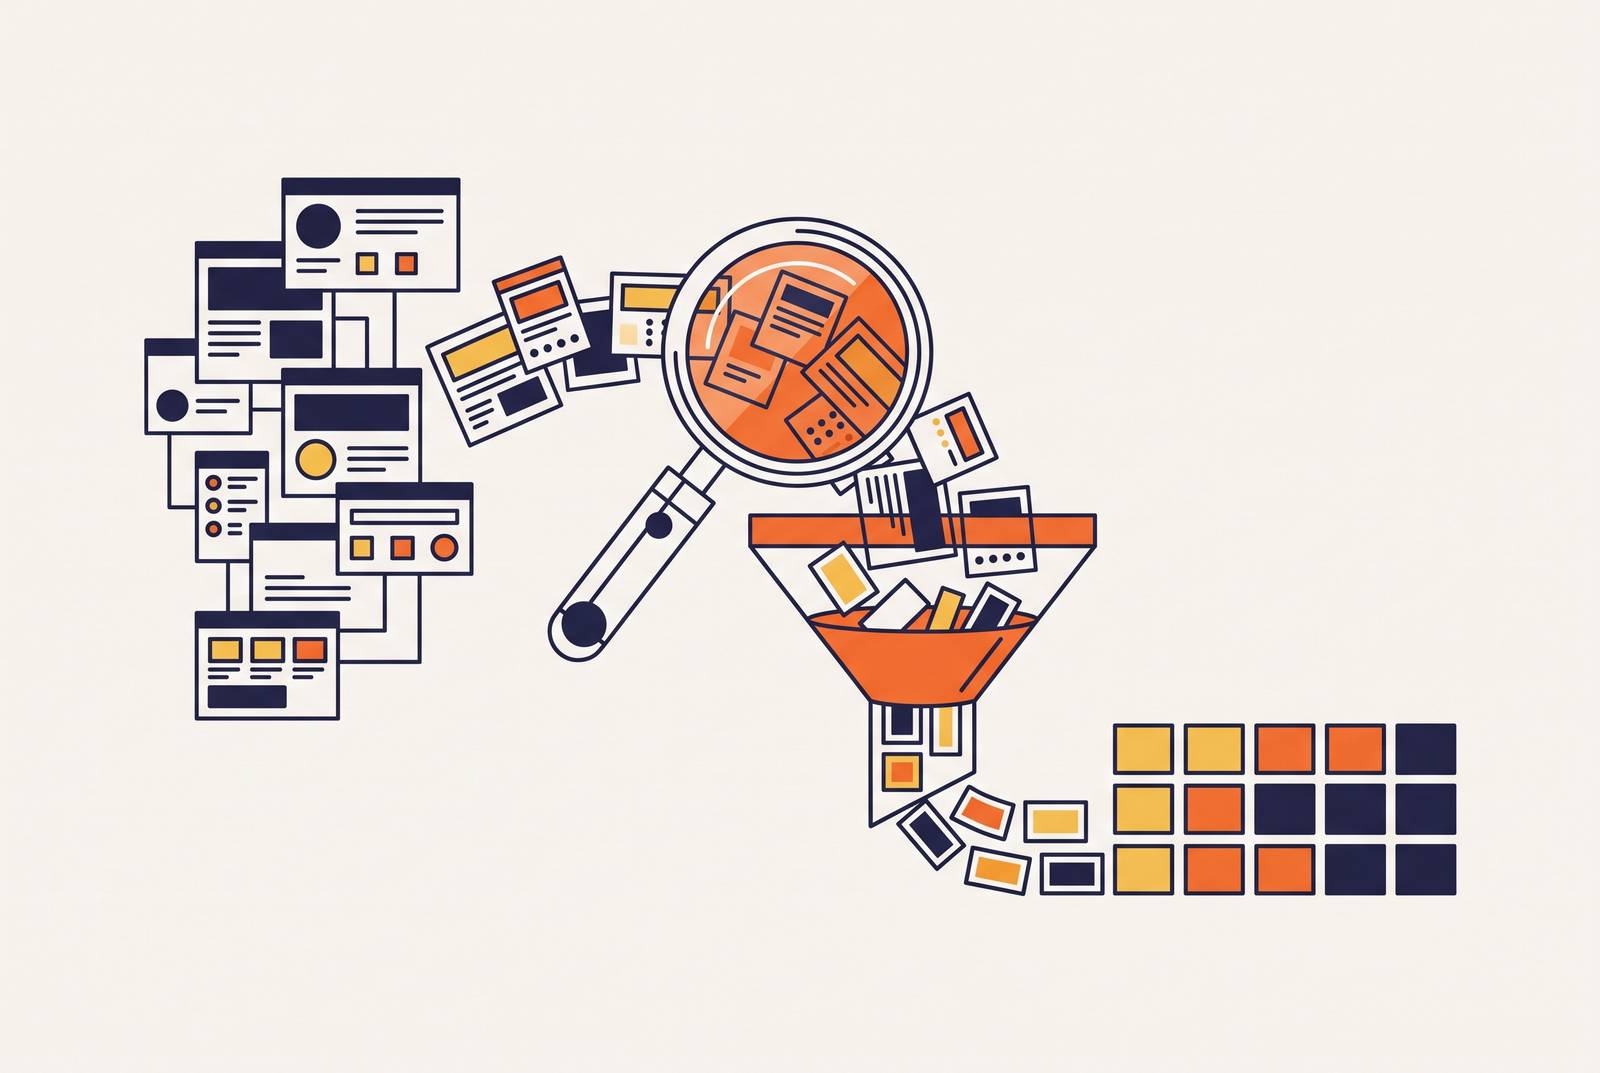
A working pipeline moves through five distinct stages, and skipping any one of them leaves a hole in the final dataset. The first stage is front-end signal collection: crawling target company pages for script tags, HTTP headers, DNS records, and other fingerprints, which is the fast, cheap, high-coverage layer that maps the visible stack. The second stage is JavaScript rendering, and for any site built on client-side rendering, a headless browser execution layer isn't optional. Skipping it means the crawl comes back empty or structurally broken, and the fingerprinting built on top of it fails along with it.
The third stage is job-posting ingestion: pulling job descriptions from career pages, job boards, and applicant tracking systems, then applying extraction logic to pick out named technologies from requirements, preferred skills, and tooling sections. The fourth stage is structured output and normalization, and it's easy to underestimate. Raw signals from both channels arrive using different names for the same thing, so "Google Analytics 4," "GA4," and "Google Analytics" all need to collapse into one canonical entry, or the combined dataset simply isn't queryable at scale.
The fifth stage is freshness cadence: re-crawling pages and re-ingesting job postings on a defined schedule, with the schedule itself shaped by the fact that different signals decay at different rates. A technology that turns over quickly needs a tighter cadence than one that barely changes year to year, and that decision should trace back to how time-sensitive the downstream use case actually is.
One more decision sits above all five stages and deserves honest treatment: whether to build this infrastructure at all. For a team without an existing scraping operation, the build-versus-buy math isn't obvious or easy. Proxy bandwidth costs alone, at large scale, can make a managed API service cheaper than running an in-house pipeline, for all but the highest-volume operations. That cost comparison is worth running before committing engineering time to any of the five stages above.
Where the legal boundary sits for public-web technographic collection
Whether scraping public pages amounts to unauthorized computer access has a fairly settled answer in most jurisdictions. The question that actually carries risk is whether the terms of the platforms being accessed create contractual exposure on top of that. Legal protection for reading public pages doesn't extend to contracts a scraper has agreed to by creating an account. Any platform where logging in comes before access opens up a separate kind of legal exposure that the "it's just a public page" argument does not cover.
Job-posting ingestion, which sits at the center of this whole approach, is on relatively solid ground here. That data typically comes from public career pages, public job boards, and public applicant tracking system listings, not from behind any login wall, and that distinction matters when weighing legal risk.
The regulatory picture gets more complicated once personal data enters the frame, even data that looks public on its face. In the EU, France's data protection authority, CNIL, ruled against KASPR over its scraping of LinkedIn contact details, finding no valid legal basis for the processing under GDPR Article 6. Secondary commentary on the ruling noted that the individuals involved had not "manifestly made public" their contact information, even though it was technically visible on a professional network. The lesson generalizes well beyond that one case: publicly visible professional data can still carry regulatory exposure, and how it's collected and used is what decides that exposure, not just whether it was visible in the first place.
Four practical habits lower that risk without requiring a legal team on retainer. Scope collection to pages that are genuinely public, with no account or login required. Respect robots.txt and ai.txt directives rather than treating them as optional speed bumps. Stay away from scraping personal contact details off professional profiles, since that's exactly the category that drew CNIL's attention. And for any pipeline that feeds its output into AI models, review the relevant EDPB guidance before scaling the operation up.
Evaluating a technographic data provider when you are not building the pipeline yourself
Not every team buying this data wants to build the pipeline described above, and that's a reasonable call for a team short on engineering time rather than curiosity. The right order of evaluation is detection method first, coverage and freshness second, delivery format third. A provider whose detection method can't see the signal type needed in the first place is stuck, because the gap is structural.
Matching detection method to use case is the real decision to get right. A use case built around front-end and infrastructure visibility is well served by a crawl-specialist provider. A use case built around backend and internal tooling needs a job-posting inference provider as the primary source. For most go-to-market teams, the honest answer is neither one alone: a provider covering both signal types, or an architecture that combines two providers, is the correct choice.
BuiltWith is a useful reference point here. Its coverage across front-end-visible technologies is broad, and it tracks historical adoption over time, which makes it a strong pick specifically for website-stack detection. Its limitation is the same limitation facing any crawl-only source: the internal stack, the part every go-to-market team actually wants to see, stays largely out of view.
None of this is a reason to treat technographic data as unreliable. It's a reason to ask any provider, including the one currently pitching a demo, exactly which layer of the stack their detection method can actually see, and to assume the rest of the stack needs a second source to fill in. That question, asked early, saves a lot of disappointment later.