Extracting and Structuring Contact Context From Company About Pages
How to extract leadership names, missions, and contacts from company About pages at scale.
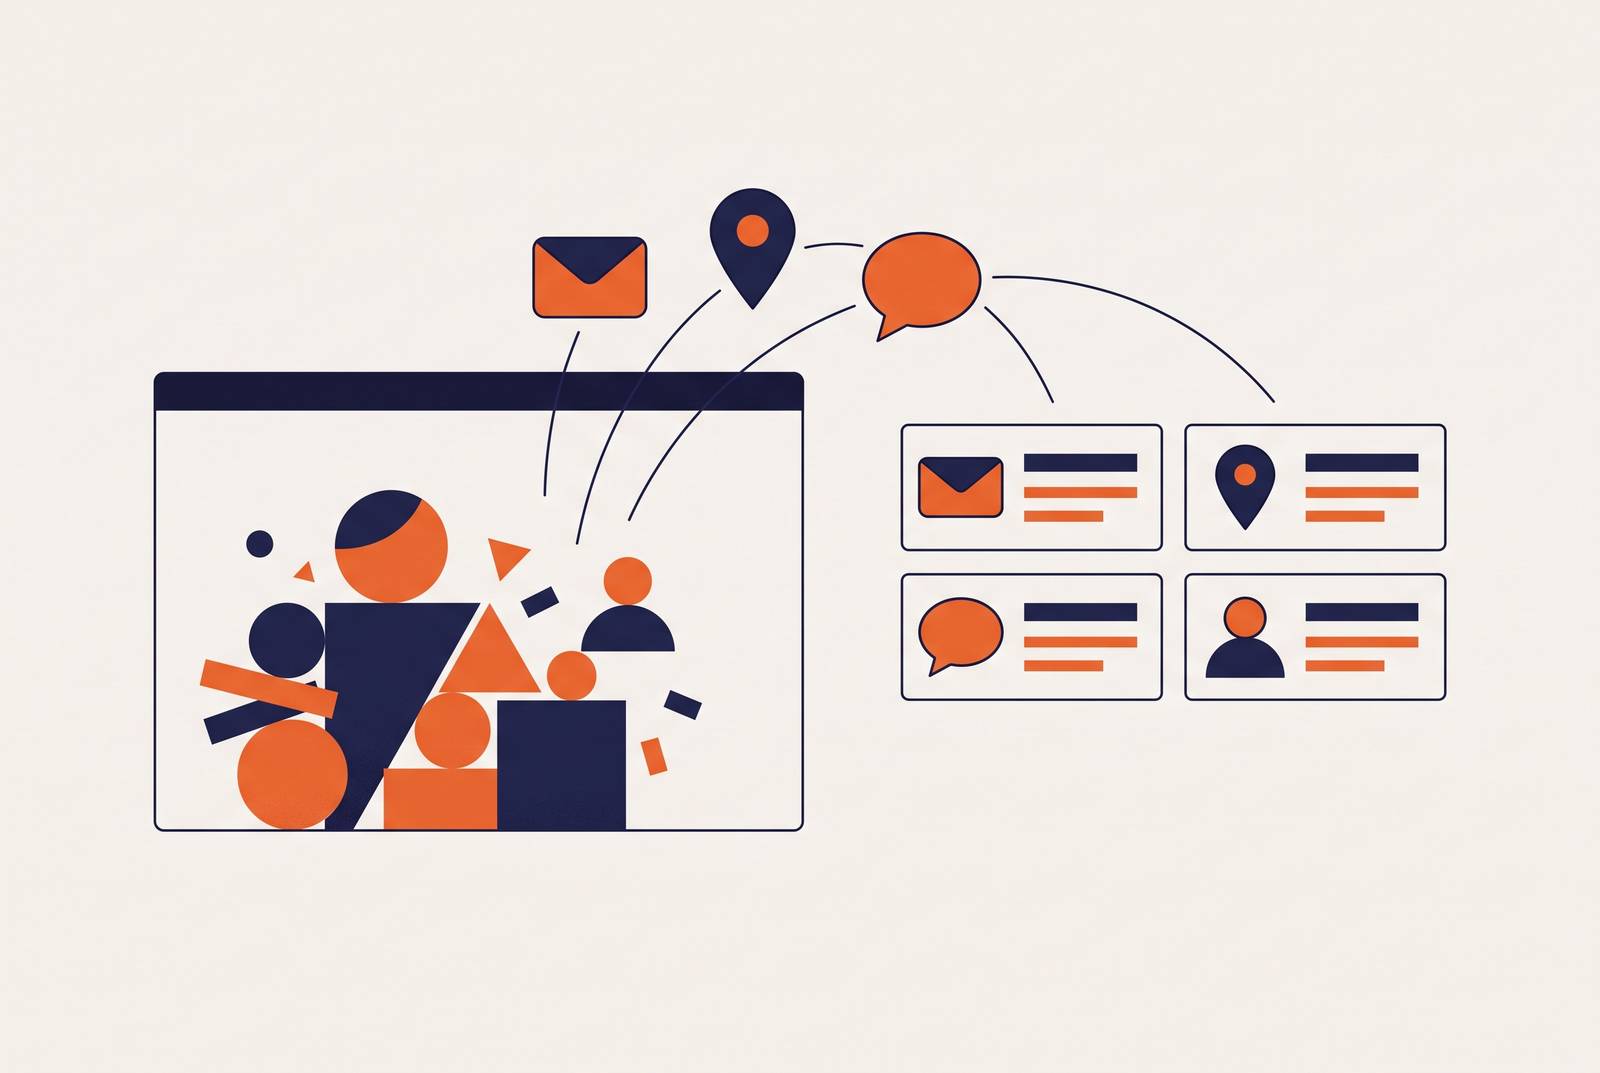
An About page is the one document a company writes about itself, on purpose, and keeps current. That single fact makes it the strongest starting point for B2B contact extraction, because it puts company identity, leadership names and titles, the founding story, mission language, and a contact route all on one page. Nobody hunts for this information at gunpoint. A company chooses to tell you who its VP of Sales is, chooses to describe its mission in language that signals exactly who it sells to, and chooses to list a phone number or a contact form. Compare that to the usual grind: bouncing between Google, LinkedIn, and map listings, each with its own format, its own gaps, its own stale fields. About pages don't have that problem, except that almost nobody processes them the same way twice.
The structural advantage is visible the moment you look at what a typical About page contains. A leadership block names the CEO, the CTO, maybe a VP of a function like partnerships, each with a title that tells you who holds budget and who holds influence. A mission statement, just three sentences long, often tells you more about ideal-customer fit than a paid data vendor's firmographic tags do. And a contact section, buried at the bottom, gives you an email, a phone number, or an address that the company itself stands behind. All of that sits in one fetch.
The obvious objection is that static databases already aggregate this information, so why bother scraping About pages. Capacity is the answer. Vendors selling hundreds of millions of contact rows can't re-verify all of them on a schedule that matters to a salesperson working a live deal this week. The record a rep actually needs might sit outside the small slice that those vendors bother to refresh. Live extraction from the company's own About page closes that gap, because the company updates it whenever leadership or mission or contact details change, not whenever a database vendor's crawl schedule gets around to it.
Why raw About page text defeats agents and downstream tools
The thing that makes About pages valuable is the same thing that makes them hard to use. The richer the page, the messier the text, and the messier the text, the less an automated system can do with it straight out of the box. A single About page can casually mention fifteen companies, thirty people, and forty product names, and plenty of those mentions are ambiguous on their face. An agent that can't sort out which name means what will act on the wrong one, and it won't tell you it did.
Three failure patterns occur repeatedly in production pipelines, and each one looks small until it breaks something downstream. A NER model tags "Senior Product Manager" from a job posting as a product entity, and the pipeline reports a new product launch that was actually a hiring page. A page mentions "John Smith" in a byline and a different "John Smith" in a customer testimonial, and the extractor merges them into one person, quietly attributing a customer's quote to a journalist who never said it. A market research crawl runs into two companies with similar names, mixes up their histories, and hands back a competitive analysis comparing the wrong businesses to each other.
Each of these traces to the same root issue: the extraction layer treated every span of text the same way, with no sense of what type of thing it was looking at, no attempt to tell two similar names apart, and no disambiguation logic. Large language models don't read raw HTML well either. They need clean, structured, context-aware input. That's why Markdown and structured JSON exist as intermediate formats, stripping a page down to its actual meaning before a model ever sees it. An agent that stuffs thousands of tokens of raw HTML into its context window also runs slow, runs expensive, and stops working entirely the first time the target page redesigns its layout.
Stage 1 — Extract (pulling typed entities from unstructured About page text)
Fixing this starts with extraction, and extraction only works if it produces typed entities with confidence scores attached, not just chunks of highlighted text. A standard named-entity-recognition model will tag "Microsoft" as an organization and stop there. An agent-ready extractor goes further: it tags "Microsoft" as a company, attaches a confidence score, suggests a canonical name, and flags whether Microsoft is the subject of the page, a named partner, or just a vendor mentioned in passing.
Three named entities, three completely different roles. The founder is a person, and she's the subject's founder. The venture firm is an organization, and it's a co-investor. Twilio is an organization too, but it's a technology partner, not an investor and not the subject. A naive extractor sees three proper nouns. A typed extractor sees three different relationships instead, and that is what matters.
This is what separates entity extraction built for agents from general-purpose NER: it's type-rich, it accounts for the fact that names need resolving, and it hands back structured records an agent can query and filter instead of a wall of tagged text. The architecture that gets this right usually runs in three layers. A fast model like GLiNER handles the first pass of span detection, and it catches custom entity types without needing to be retrained for every new category. A large language model steps in only where ambiguity needs context, like deciding whether "Amazon" means the company or the river. A resolution layer then links whatever survives to canonical records. Pipelines built this way, extract then resolve then structure, consistently beat single-pass LLM extraction on both recall and precision when a page mentions a lot of entities at once.
For About pages, three entity types matter most: person, with title and department attached; organization, tagged as either the subject of the page or a named partner; and contact route, meaning email, phone, or address. Define those as fields before you write a single line of extraction logic, the same way you'd turn each trait of your ideal customer profile into a field the schema has to fill. And know where to spend the expensive compute. Hard facts like an email address or a phone number don't need an LLM; deterministic pattern matching is faster and cheaper. Context-heavy judgment calls, like whether a paragraph signals a strong ICP fit, are where the LLM earns its keep.
Stage 2 — Resolve (disambiguating entities against canonical knowledge bases)
Extraction finds things. Resolution figures out what they actually are, linking a record to something a CRM can actually use instead of leaving it sitting in a spreadsheet. An entity that's merely been found is a guess with a label on it. If an entity has been resolved, though, it's linked to something real, something a sales team's existing systems can recognize and match against.
Consider a page that mentions "AWS," "EC2," and "cloud computing" in three separate sentences. A naive extractor tags three unrelated entities. A resolution layer recognizes that EC2 is an AWS product and that "cloud computing" is a category, not a company, collapsing the useful signal into one record, Amazon Web Services, with a boosted confidence score, which is the work resolution does. It links each entity to a canonical source, whether that's Wikidata, Crunchbase, or a company's own internal knowledge base, and it's what lets the structuring stage that follows output JSON an agent can actually trust and act on.
People need the same discipline, maybe more of it. When a page mentions "John Smith" twice and there's any chance they're two different people, the system should produce two separate contact cards and ask for confirmation rather than quietly merging them into one. Getting this wrong is how a customer quote ends up attributed to a journalist.
None of this works without provenance built into the resolution stage itself, not bolted on afterward. The pipeline has to record which URL an entity came from, which page it was published on, and what confidence score it received, so a record can be checked and corrected later without anyone having to re-fetch the original site. The output contract at this stage carries, for each resolved entity: the extracted name, the canonical name, an external identifier (a Wikidata ID, a Crunchbase slug, or an internal CRM ID), the entity type, the source URL, and a confidence score.
The common pushback is latency: doesn't all this lookup and cross-referencing slow things down? Not when the resolution layer is built for the job instead of improvised on top of a general-purpose LLM call. Sub-500-millisecond resolution per page is achievable, which is fast enough for an agent working in real time, not just for an overnight batch job.
Stage 3 — Structure (producing agent-ready output that downstream tools can consume without post-processing)
Structure is the contract that decides whether a vector store, a CRM sync, an MCP tool call, or a knowledge graph can use a record as-is or whether someone has to write glue code to translate it first. Schema-driven extraction with typed entity contracts is what lets all of those downstream tools consume a record without a post-processing step standing in the way.
That earlier paragraph about the founder, the venture firm, and the technology partner shows the shift. Raw, it's just a sentence of prose sitting inside an HTML <div>, buried under a navigation bar and a cookie banner. Structured, it becomes something like:
{
 "person": {"name": "Maria Chen", "role": "Founder", "confidence": "confirmed"},
 "organizations": [
 {"name": "Sequoia Capital", "relationship": "investor", "confidence": "likely"},
 {"name": "Twilio", "relationship": "technology_partner", "confidence": "confirmed"}
 ],
 "source_url": ",
 "extracted_at": "2024-XX-XX"
}
That record is immediately queryable. A sales rep's agent can ask "does this company have a named investor" and get a straight answer instead of having to re-read a paragraph.
Two formats dominate here, and each has its own job. Markdown keeps a page's semantic structure intact, headings stay headings and lists stay lists, which makes it a good fit for retrieval pipelines that feed a vector store, once the boilerplate is stripped out. Schema-validated JSON is the right choice when a downstream tool needs to filter, route, or act on a specific field without parsing a paragraph of prose to find it.
A complete structured contact record pulled from an About page should carry: company name, a canonical identifier, the primary contact's name and title and department, an email address labeled confirmed, likely, or unverified along with its source URL, a phone number with the same labeling, a physical address, the source page URL, an extraction timestamp, and a confidence score attached to each individual field.
Row-level provenance matters as much as field-level detail. The output should keep one row per input URL, including duplicates, sites with no email listed, and scans that failed outright, so the export can be joined back to the original list by row or by URL. An empty result is a finding: it tells an agent to try a fallback source or flag the company for a human to look at, instead of just vanishing from the dataset. And because pages change layout, go offline, or get redesigned without warning, the schema itself needs drift detection and ongoing monitoring, the same discipline a company would apply to any production system that depends on an uncooperative outside world. The tools waiting on the other end of this, CRM sync platforms like Salesforce and HubSpot, vector stores for retrieval, knowledge graphs, and MCP servers exposing the record as a tool call result, all expect data in this shape. Give it to them any other way, and someone ends up writing a parser at 11pm.
Provenance and reviewability as pipeline requirements, not features
A pipeline that can't answer "which site did this come from, and what happened when nothing turned up" isn't ready for production, no matter how accurate its extraction looks on a demo slide. Accuracy without an audit trail is a magic trick, not a system.
In ordinary crawlers, the tool returns only the records where it found a match, producing a clean, compact result file that looks great until someone tries to reconcile it against the original input list. If a URL was broken, a site blocked the fetch, or no email ever appeared on the page, that row just isn't there anymore. Nobody flagged it, nobody logged it, it's just gone. Someone then has to guess which of three very different situations happened, a skipped site, a silent failure, or a genuine no-result, and guessing is not a review process.
The fix is structural: one output row for every input URL, no exceptions, with a status field that says found, not found, fetch failed, or access blocked, so those three situations never collapse into one unreadable blank. Every field in that row should carry its own label, confirmed, likely, or unverified, with the source URL attached, so a human reviewer or an agent can check any single field on its own without re-running the entire pipeline from scratch.
This has a direct, practical payoff on the CRM side. Records that come back confirmed flow straight into Salesforce or HubSpot automatically. Records that come back low-confidence route to a human review queue instead of polluting the CRM with a guess dressed up as a fact. Fixed schemas, explicit "none found" rules, email verification, deduplication, and a review queue for shaky data are the baseline a pipeline has to clear before you should trust its output.
Turning the About page pipeline into a live MCP tool call
Everything described above, extract, resolve, structure, has historically run as a scheduled batch job: crawl a list overnight, process it, drop a file somewhere by morning. The Model Context Protocol changes that shape. So instead of a pipeline running on a schedule, About-page extraction becomes a single tool call an agent makes on demand. Point an agent at a company's URL; within one session it pulls the About page, extracts typed entities, resolves them against canonical sources, and pushes a finished record straight into a CRM, no overnight batch required.
MCP was introduced by Anthropic in November 2024 and now sits under the Agentic AI Foundation, a directed fund under the Linux Foundation. It gives agents a standardized way to call external tools and get structured results back, so the three-stage pipeline described here stops being a backend process that nobody outside engineering ever sees. It becomes a capability an agent reaches for mid-conversation, the same way it might look up a stock price or check a calendar. The pipeline doesn't change. What changes is who gets to call it, and how fast the answer comes back.