Extracting Structured Data From JavaScript-Heavy Competitor Sites
Render the page first, then navigate bot detection and database integration.
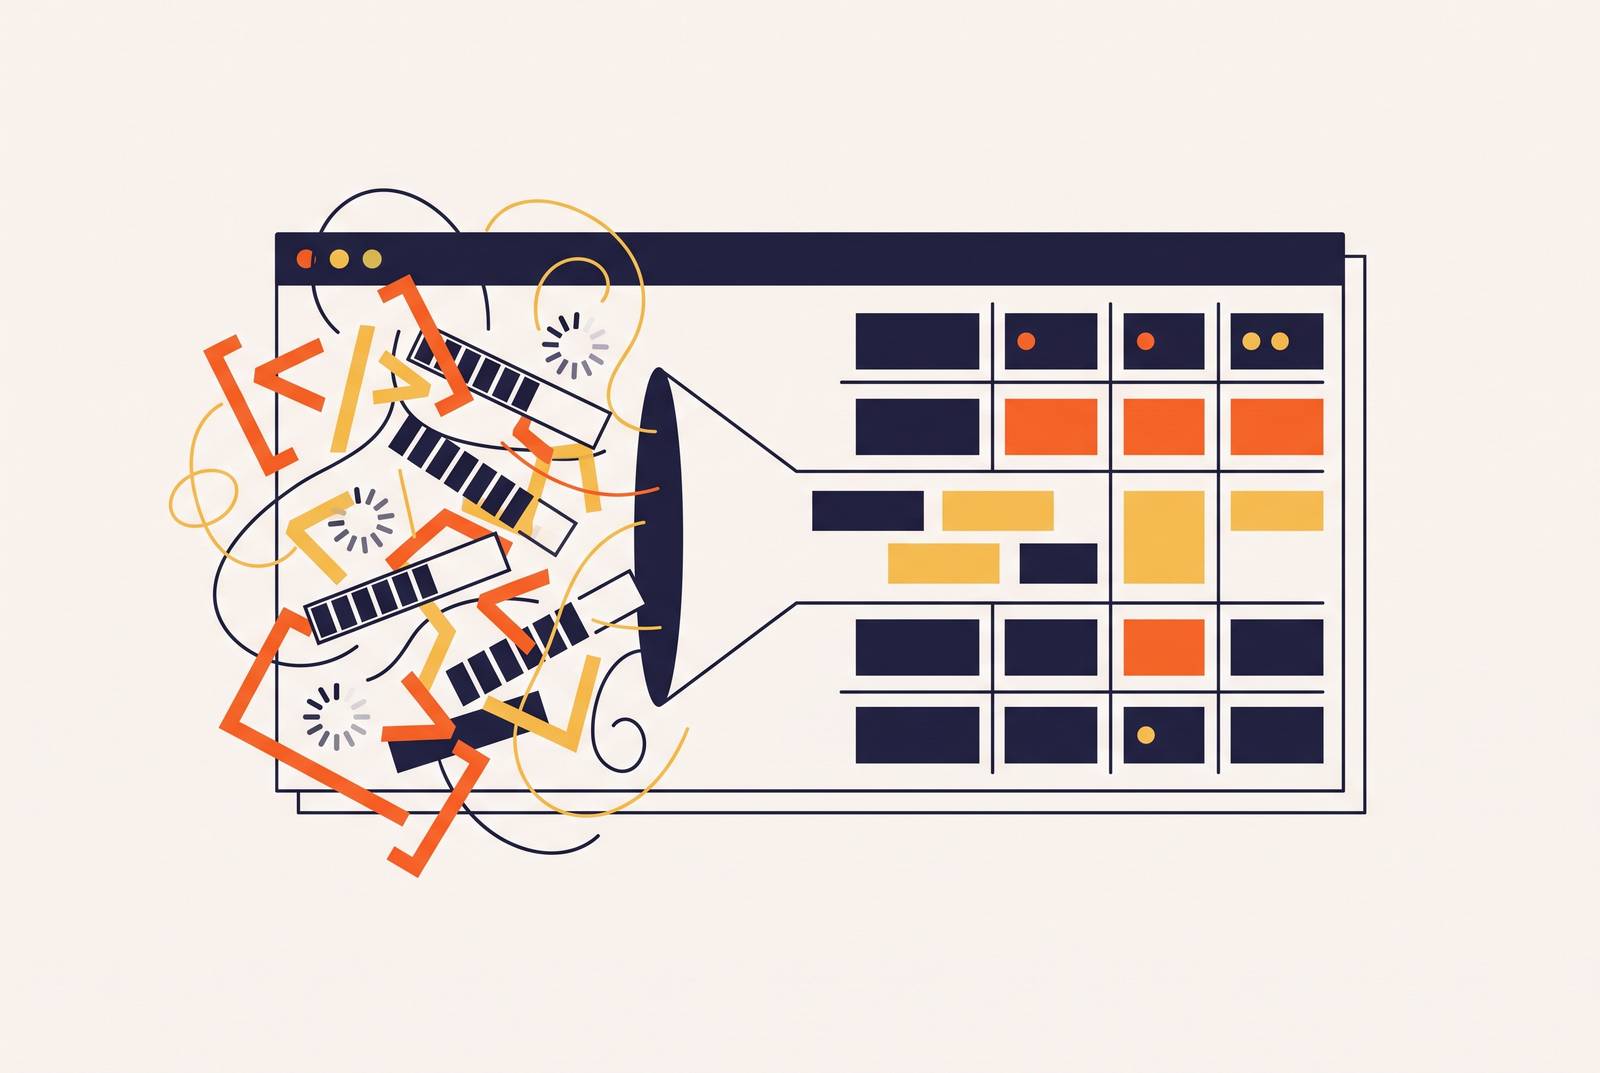
The core mistake teams make with JS-heavy scraping is treating a rendering problem like a parsing problem. It's treating a rendering problem like a parsing problem, and then wondering why a week of rewritten CSS selectors changed nothing. Data extraction here is three stacked jobs: render the page like a browser would, get past whatever's guarding it, and turn the result into something a database or an AI model can use. Skipping a layer breaks the whole pipeline in a way that looks like a completely different problem, which is exactly why so many teams end up debugging the wrong thing for months.
Start with the diagnosis. A site counts as "JS-heavy" when the data you want isn't in the first HTTP response at all. The server ships a skeleton, and JavaScript fills in the rest afterward, in the browser, on the user's machine. Three patterns cause this over and over. Single-page apps swap content in and out without ever reloading. Infinite scroll only loads rows as you scroll toward them, so nothing past row twenty exists in the raw HTML. And plenty of sites fetch their real data from a separate backend endpoint after the page loads, then inject it client-side, so the page you see in a browser and the document a basic scraper receives are two different things entirely.
Point a classic scraper (requests plus BeautifulSoup, or whatever the equivalent is on your stack) at any of that and it sees an empty shell. No prices, no review counts, no competitor catalog rows. Just a script tag and a loading spinner that will never spin, because there's no browser there to run the script that makes it spin.
This isn't a fringe case. Industry analysis puts the share of sites built on frameworks like React, Next.js, or Vue above 70%. The empty shell is the default state of the modern web, not an edge case you occasionally trip over. Parsing assumes the data already showed up and you just need to pull it out of the tags. Rendering is about getting the data to show up in the first place. Confuse the two and you'll spend a week polishing selectors for a page that was never going to have the data no matter how cleverly you pointed at it.
Rendering is only step one, too. Even after a page fully loads, there's a second wall waiting: bot detection. And a third wall after that: making the result usable by anything downstream. Each one fails differently. Each one needs its own fix, and none of them substitute for each other.
What the rendering layer must do, and where headless browsers fit
Getting data off a JS-heavy page requires something that acts like a real browser: runs the JavaScript, waits for the page to settle, then hands over the finished DOM. That's the entire job of a headless browser. There's no shortcut around it, reverse-engineered API calls aside (more on that in a second).
Three tools dominate here, and they're not interchangeable, whatever the comparison blog posts imply. Playwright, built by Microsoft, drives Chromium, Firefox, and WebKit from one API, which makes it the right call when you need to test or scrape across browser engines without maintaining three separate codebases. Stealth plugins like playwright-stealth bolt on some basic bot-detection resistance, though "basic" is carrying a lot of weight in that sentence. Puppeteer sticks close to Chrome and Chromium, talking directly to the DevTools protocol, and picked up official Firefox support through WebDriver BiDi starting with version 23. It's the tighter, faster pick if a single browser engine covers your use case. Selenium is the oldest of the three, with the widest language support and the deepest ecosystem, but it also carries the most maintenance weight when a modern single-page app throws it something unexpected.
None of this comes free. Each headless Chrome instance eats somewhere between 200 and 500 MB of RAM, and that adds up fast once you're running dozens of instances instead of one. Running this at the scale a real competitor-monitoring operation needs means the server bill stops being a rounding error on someone's budget. Headless mode itself cuts resource use by up to 40% compared to a full visual browser window while still giving complete DOM access, which is part of why "headless" became the default rather than a special mode reserved for CI pipelines.
Reverse-engineering a site's own API calls is a real shortcut, but it's not something to build a foundation on. Plenty of JS-heavy sites pull data from an internal JSON endpoint, and if you spot that call in the network tab and reproduce it directly, you skip rendering altogether. Fast when it works. It only works until the site changes something: an obfuscated payload, a rotating URL, a header that shifts without warning. Treat it as a bonus when you stumble onto it rather than a strategy to build a production pipeline around. The maintenance burden of chasing a moving endpoint tends to erase whatever speed you gained chasing it in the first place.
And here's the ceiling on doing all of this yourself: getting the browser to render the page solves exactly one problem. Proxy rotation, fingerprint management, scaling to hundreds of concurrent sessions, all of that is still sitting there unsolved. Now it's your team's job.
The bot-detection stack that intercepts headless browsers before they reach the data
Automated traffic made up more than 53% of all web traffic in 2025, Imperva's Bad Bot Report found. Sites are building defenses sized for a world where the majority of visitors to a page might not be human at all, using data instead of guesswork about bots. They're building defenses sized for a world where the majority of visitors to a page might not be human at all.
Five layers do the actual catching, and they stack on top of each other rather than working alone. IP reputation checks flag datacenter ranges and known proxy pools as one of the first signals evaluated. TLS fingerprinting, using a method called JA4 (the successor to JA3, built after Chrome started randomizing the order of TLS extensions in Chrome 108, late 2022), reads the structure of the handshake itself: the cipher suites offered, the elliptic curves used, to figure out what's really making the request no matter what the User-Agent string claims. Cloudflare, Akamai, and AWS WAF all use JA4 as one signal among several, though Cloudflare keeps it behind its Enterprise Bot Management tier.
Browser fingerprinting digs into canvas rendering, WebGL output, installed fonts, and hardware concurrency, all things a headless browser tends to expose in small, telltale ways. Behavioral analysis watches how a mouse moves, how fast someone scrolls, how evenly spaced the requests come in. CAPTCHAs sit in front of the highest-value pages as an additional human verification layer.
Rotating a few IPs and setting a convincing User-Agent used to be enough, back when that kind of setup could clear a basic defense. That approach gets caught in seconds now, by any protection layer. Proxyway's 2025 Web Scraping API Report found that on Shein, G2, and Hyatt, three of the harder targets tested, average success rates stayed well below half even at modest, polite request rates. These are exactly the kind of pages a competitor-monitoring pipeline needs to hit. They're exactly the kind of pages a competitor-monitoring pipeline needs to hit.
The pages worth scraping, pricing tables, review aggregators, product catalogs, are the same pages that get the most expensive defenses. The WAF market represents a substantial, well-funded industry built specifically to keep scrapers out, and it treats every layer above as one piece of a coordinated stack that must be cleared together.
Running evasion in-house means someone on the team is now on permanent fingerprint patrol, tracking which signal changed this week and rewriting around it. That's the actual hidden cost of DIY scraping. Not the build. The weekly hours spent chasing a target that keeps moving the goalposts.
How managed scraping APIs absorb the rendering and evasion layers so the pipeline starts at clean data
Providers in this space split into two camps. One hands back raw HTML and leaves rendering and parsing to you. The other, built more recently and aimed squarely at AI workflows, hands back clean Markdown or structured JSON already stripped of the noise. Same category of problem, very different product waiting on the other end.
A handful of names appear consistently in 2026 benchmarks, each with a distinct edge. Zyte took the top unblocking score in Proxyway's 2025 benchmark, holding a strong success rate at two requests per second, and only charges for requests that actually succeed. That matters when a target is defended enough that half your calls would otherwise fail on your dime instead of theirs. It's the right pick when success rate per dollar affects total cost more than raw network size does.
Some providers run on a credit system instead: a plain request costs one credit, a request needing full page rendering costs ten, an ultra-protected target might run seventy-five. That model tends to win on price for teams fine with handling raw HTML and doing their own parsing after the fact. Others run a marketplace model, hosting pre-built scrapers for specific, well-known targets like Instagram or Google Maps, which is the right call when the scraper you need already exists and writing extraction logic from scratch is just reinventing a wheel somebody already built.
The market's direction says something too. Industry projections put the web scraping API space growing at a 17.39% compound annual rate from 2026 to 2031. The market's direction says something too: that figure shows this is a shortcut picking up real traction. That's the center of gravity moving toward managed infrastructure as the default option.
There's still a narrow case for running headless browsers in-house: unusual target-specific quirks, internal rules about routing data through a third party, or genuinely low-volume one-off pulls where setting up a vendor relationship costs more than the scrape itself. It's a real case. It's also a shrinking one, and betting a whole pipeline on it is the wrong call for most teams.
Turning rendered, unblocked page content into structured data an AI pipeline can consume
Rendering and access solve two of the three problems. Format is the third, and it affects extraction accuracy just as much as the other two. NEXT-EVAL's 2025 benchmarking found LLMs hitting F1 scores above 0.95 on structured web extraction, but only when the input was formatted properly first. Feeding the same model raw HTML drops the score hard. The model was never the bottleneck. What gets fed to it is.
Raw HTML fights an AI pipeline on three fronts at once. It's expensive to process: Firecrawl's own comparison of clean Markdown against raw HTML found a 67% reduction in token count, a difference that compounds fast once you're processing pages by the million. It's noisy, packed with nav bars, cookie banners, ad slots, and script tags that have nothing to do with the actual data and actively confuse a model trying to reason about what matters. And it's structurally meaningless to a language model. A div nested six levels deep inside a class called wrapper-inner-2 tells a human developer nothing, and it tells an LLM even less.
Three output formats solve this, each in a different way. Clean Markdown keeps the document's real structure (headers, lists, tables) while cutting the token overhead, which makes it the right pick for feeding an AI agent's context window or grounding a retrieval system. Structured JSON built against a defined schema gives typed fields you can validate and drop straight into a database or vector store, which is what a price-monitoring or catalog-comparison pipeline actually needs, since the task isn't summarizing a page, it's querying specific fields against each other. Raw HTML still has a place, but only when the next step is a specialized parser your own team already owns, not as a default choice.
Instead of writing CSS selectors that break the moment a competitor's designer renames a class, define a model (a Pydantic-style schema is the common approach) describing exactly the fields wanted: price, currency, review count, stock status. The extraction layer maps the page onto that schema. Changing the layout lets the mapping adjust on its own. That's the whole point: the selector approach breaks on redesign, the schema approach survives it, because it's asking "what does the price field say" instead of "what's inside the third span in the second div."
A paper out of Cairo University (AXE) paired a small, 0.6B-parameter model with intelligent DOM pruning, cutting input tokens by 97.9% while still hitting an F1 of 88.1%. The lesson there is that cleaning the input properly does more for accuracy than throwing a bigger model at a messier page ever will." It's that cleaning the input properly does more for accuracy than throwing a bigger model at a messier page ever will.
For competitive intelligence specifically, structured output is a foundational requirement, not merely a formatting choice. It's the thing that makes the comparison work at all. "Is competitor A's price higher than last week's" is a query against two clean fields. Running that same question against raw HTML turns it into a research project.
How AI agents and self-healing pipelines change the maintenance economics of competitor monitoring
The old math on scraper maintenance was rough: the build itself was a fraction of the effort, with the majority of engineering time going into keeping a scraper alive as target sites changed layouts, rotated selectors, or updated defenses. The real cost of scraping was never the build. It was the babysitting afterward.
Self-healing extraction flips that ratio around. An LLM watching the page can spot a layout change as it happens and re-map extraction logic without a human touching the code. A competitor tweaks a CSS class overnight, and instead of the pipeline quietly returning stale or blank data the next morning, the agent adjusts and keeps pulling the right fields. McGill University research found one automated extraction approach holding 98.4% accuracy through page-structure changes, with setup time dropping from weeks to hours.
Part of what's enabling this is a shift in how agents talk to tools, through the Model Context Protocol. Voidmob.com reports MCP's SDK usage went from a modest download count at its November 2024 launch to a figure many times larger, with more than 10,000 public MCP servers now live, a good chunk of them built specifically for web fetching and extraction. What MCP actually changes is mundane but real: instead of hand-writing a wrapper around every API an agent needs to call, the agent reads a tool's schema at runtime and figures out how to use it on its own. Multiple providers already offer MCP-compatible scrapers, and agent frameworks like CrewAI support the protocol across several transport types.
The practical shift is from "write a scraper for this competitor's pricing page" to "tell the agent what data is needed and let it handle discovery, rendering, and extraction on its own." Zyte's 2026 Web Scraping Industry Report describes AI showing up across the entire lifecycle now, planning, crawling, unblocking, extraction, validation, and notes that most developers already use AI somewhere in their process. What that means day to day for a competitor-monitoring setup is a real change in where the human spends time. Instead of fixing a broken selector at 9 AM because a competitor redesigned their pricing table overnight, the job becomes reviewing what the data is actually saying. The pipeline stops looking like a fragile script somebody has to nurse along, and starts looking like a service somebody checks in on.
Putting the pipeline together: a practical architecture for JS-heavy competitor data extraction
Zooming out collapses the whole thing into three layers, each with one job and zero overlap between them.
Rendering comes first: get the JavaScript to run and the DOM to settle, whether that's a headless browser run in-house or a managed API with rendering built in. Layer two is access: get past IP reputation checks, TLS fingerprinting, and behavioral analysis, which in practice means either a serious residential proxy network or a unified API handling all of that under the hood so nobody's maintaining it by hand. Layer three is structured output: convert whatever the DOM handed back into clean Markdown or typed JSON before it ever reaches a model, with schema-defined extraction doing the heavy lifting instead of brittle CSS or XPath selectors.
Choosing the specific tools in each layer comes down to two questions. First: how defended is the target? A lightly protected competitor blog needs a fraction of the infrastructure a heavily defended e-commerce pricing page demands, and building for the second scenario when the first is all that's needed just burns budget for nothing. Second: what's consuming the output on the other end? A human analyst skimming a weekly report wants something very different from an AI agent comparing today's price field against yesterday's stored value in a database.
Getting those two questions right turns the pipeline into a system that mostly runs itself, because the human checks in on the conclusions instead of babysitting the plumbing that produces them.