Detecting Pricing Page Changes Across a Competitor Set
Automate competitor pricing monitoring with scheduled scraping and smart alerts.
An event-driven web scraping API with webhook support works for competitor pricing monitoring when it links scheduled fetches to structured comparisons and sends notifications when changes matter. Detecting Pricing Page Changes Across a Competitor Set is an infrastructure problem first. The dependable design is a crawl-diff-alert pipeline that validates pricing data, compares it with prior snapshots, and delivers useful changes to the people or systems that can act on them.
Why monitoring competitor pricing pages is an infrastructure problem, not a research task
A forwarded proposal reveals a competitor’s new price before the team’s spreadsheet does. Someone checked that pricing page last week, but the competitor repriced afterward. Nothing in the manual process failed visibly. A person opened a browser, copied numbers, and passed them along, just as planned. The plan was the weak link.
Pricing pages change on no schedule a researcher can predict. A competitor can restructure tiers, remove a discount, or introduce a limited-time offer between visits. Bundled discounts, usage-based tiers, and regional variants make a handful of spot-checks incomplete even when the headline price is current. Competitive understanding quietly drifts behind the market. Fixing that gap requires scheduled fetching, structured extraction, comparison against prior state, and routed alerts.
What a crawl-diff-alert pipeline looks like as a whole before diving into its parts
The architecture reads from left to right as Fetch → Compare → Route. Fetch visits each pricing URL on its assigned schedule, extracts structured content, and stores a timestamped snapshot. Compare checks that snapshot against the prior one at the level of prices, plans, features, and CTA copy. Route sends meaningful changes to Slack, email, a CRM, a pricing model, or an agent. Each stage has a distinct job to do.
The system runs continuously through scheduled checks, updating its baseline for the next comparison. That does not mean every page is fetched constantly. Fetching can fail or return stale content, comparison can manufacture noise, and routing can overwhelm its recipients. Keeping those jobs separate makes it easier to find where each failure happened.
Building the fetch layer: scheduled crawling across a competitor URL set
The fetch layer starts with a curated inventory of actual pricing URLs. Those addresses need maintenance as competitors reorganize their sites. Each URL also needs a schedule suited to its signal, with pricing generally checked daily or more often and positioning content checked weekly. A cron job can start a request on time. It cannot, by itself, make the response useful.
Many pricing pages render their content through JavaScript, so a plain HTTP request returns a shell without the prices. Those pages require headless browser rendering. Commercial sites with strong defenses can also check TLS fingerprints, behavioral signals, and JavaScript challenges before they serve content. For a set that includes those targets, the infrastructure needs proxy rotation, browser fingerprint management, and retry logic.
Even a successful HTTP response can be useless. A 200 response containing a CAPTCHA or bot-detection redirect must not become a pricing snapshot. The fetch layer should validate that pricing content arrived, then return clean Markdown or JSON with surrounding DOM noise removed. That validation separates “the server answered” from “the pipeline learned something,” which are regrettably different achievements.
Structuring what you extract so the diff step is actually comparing the right things
The extraction schema determines what the pipeline can recognize. It should name plan names, per-plan prices, billing cadence, included features, usage limits, trial or freemium terms, CTA copy, and promotional language. A locale field is also needed where countries or currencies produce different offers, and the crawl must account for geo-targeting. Otherwise, a regional difference can masquerade as a price change.
There are two main extraction approaches, with different maintenance costs. CSS/XPath selectors are fast and cheap per page, but a redesign can leave them returning nothing or the wrong values. LLM-based extraction reads content rather than depending on DOM structure, making it more tolerant of redesigns. It costs more and adds latency, but reduces maintenance burden for sets of dozens to hundreds of pages. That trade-off is less attractive at millions of pages.
The schema should be the same for every competitor in the set. Competitor A’s Pro plan and Competitor B’s Growth plan can keep their names while using fields that are defined the same way. JSON gives the comparisons that come next clear fields to work with. It can also improve factual accuracy over Markdown when used as LLM context in some tasks, though that advantage depends on the task and model and is not consistent across benchmarks.
Running the diff: comparing snapshots in a way that filters noise and surfaces meaningful change
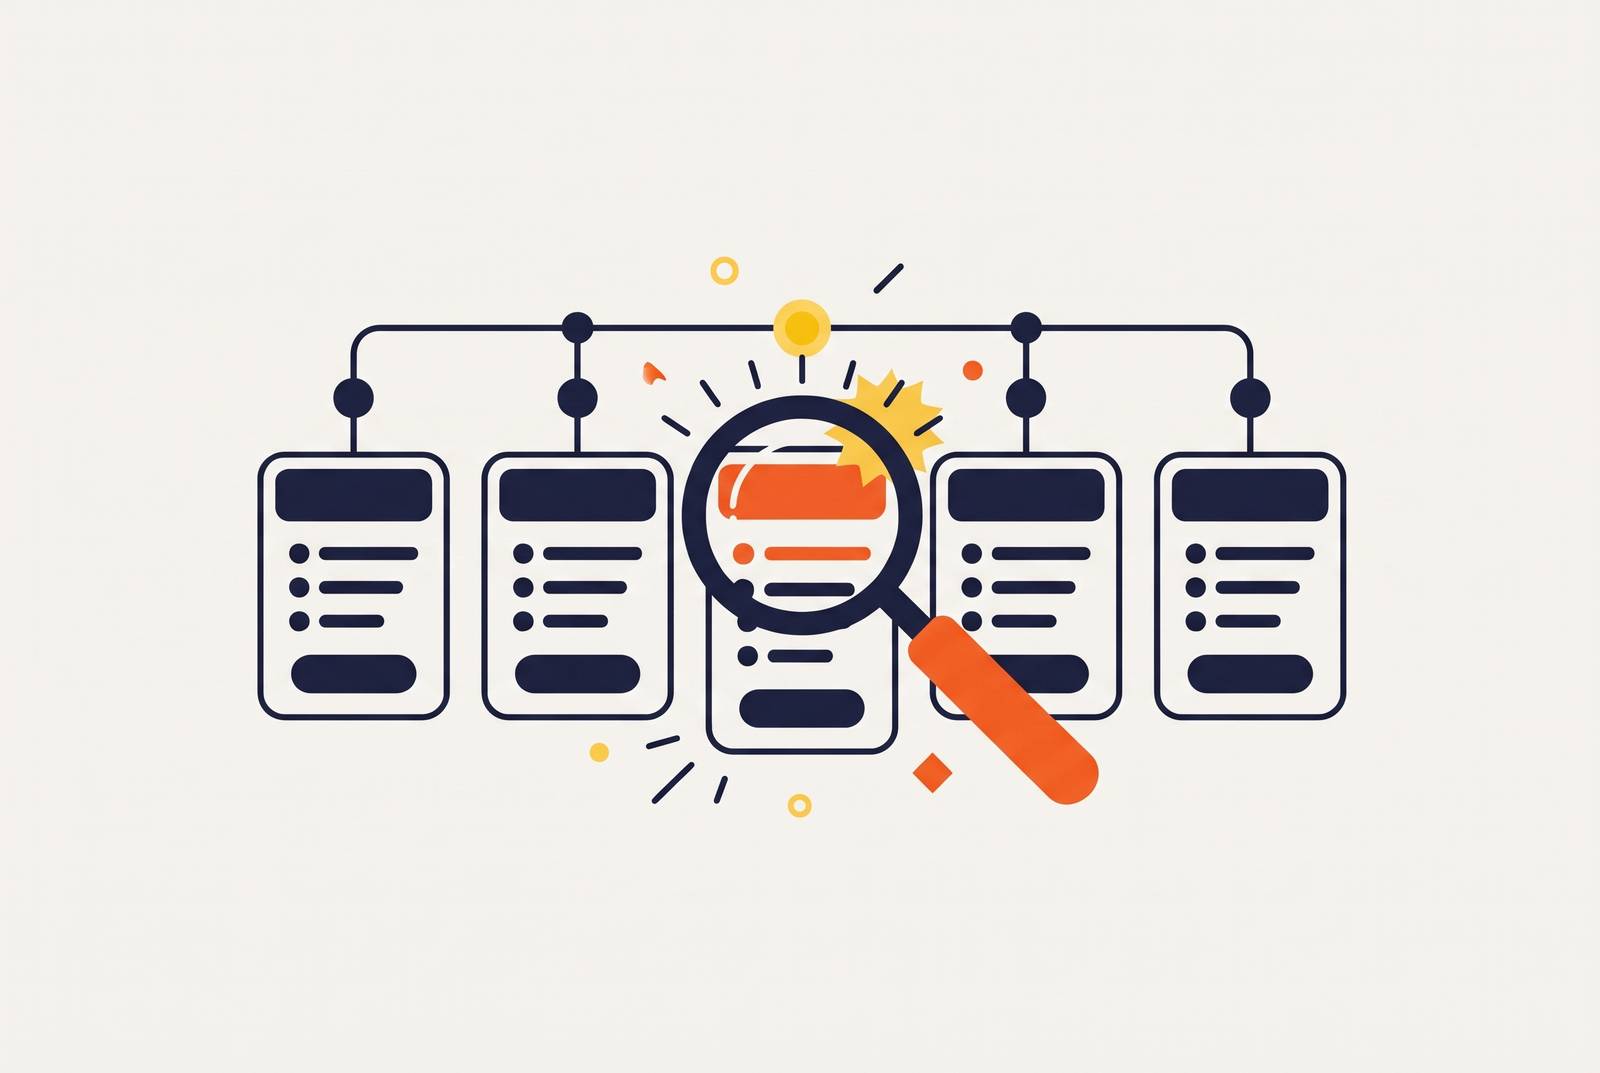
An HTML diff flags a changed CSS class. A structured diff flags a changed Pro plan price. Only one belongs in a pricing conversation. Comparing full-page text has much the same problem because it picks up footer edits, cookie banners, and navigation changes even when the offer stays put. Comparing named fields removes much of that noise before the alert rules take over.
Each validated fetch should produce a timestamped snapshot for comparison with its predecessor. The comparison needs to catch changes in both values and structure, including plan keys that are new or missing. For prose fields, semantic similarity can help distinguish a meaningful feature rewrite from a punctuation edit. A string diff alone cannot make that distinction. The comparison should run immediately after a successful fetch.
Every result needs an audit trail, even when nothing has changed. The log should keep the timestamp, competitor URL, and the old and new field values. That evidence lets sales or pricing teams trace when the pipeline detected a repricing. A notification starts the conversation. The record supports it.
How do you get notified via webhook without creating alert noise?
Webhook delivery belongs in the routing stage, after the pipeline has identified a meaningful difference. A completed fetch is not itself a pricing alert. The scheduled crawl discovers the current state, the comparison detects a change, and the webhook delivers that result to a downstream consumer. Treating those as separate events avoids confusing “data arrived” with “someone needs to act.”
An alert should contain the competitor name, URL, changed field, prior value, new value, timestamp, and a plain-language explanation. A drop in the price of a core plan should go to pricing leadership and competitive intelligence right away, while a feature update should go to product. CTA edits may deserve a log entry without a notification. Changes to headline pricing have high priority, while changes to an annual discount or usage cap can have medium priority.
The routing rules need a materiality threshold. Cosmetic changes below that threshold should stay out of notification channels. Structured output can instead update a CRM field, trigger a battlecard refresh, feed a pricing model, or start an agent workflow. The right destination depends on the change. Otherwise, the pipeline becomes a very punctual reason to mute Slack.
Choosing monitoring cadence and scope for a competitor pricing set
Alert filtering cannot fully compensate for an unnecessarily broad monitoring scope. Tracking a competitor’s pricing page keeps the comparison focused, while homepages, blogs, and job boards belong in separate monitors with their own schedules and routing. Different signals deserve different treatment.
SaaS pricing pages in active markets need checks every day or more often, while annual contract pricing pages that rarely change can be checked weekly with little loss of coverage. Direct competitors that come up in active deals need to be checked most often. Checks on adjacent or emerging competitors can run less often, which cuts needless load and gives more time to the companies that matter most right now.
The inventory itself also needs periodic review. Competitors move pricing pages, add products, and stop using old URLs, so checks can run on time and still go to the wrong address. Sitemap crawls or search-results-based discovery checks can partially automate that review.
Where the pipeline breaks in production and how to make it resilient
The most dangerous production failure is silent degradation. A changed anti-bot setup can turn valid fetches into CAPTCHA pages or empty responses. If those responses enter storage, the diff may compare two bad snapshots and report no change while the real pricing page moves on. Expected-content validation must therefore happen before snapshot storage, with failures logged as a separate alert class.
Schema drift needs a similar safeguard at extraction time. A redesigned page can break selectors, while even LLM-based extraction needs checks for field completeness. When required fields, such as price or plan name, are missing, the result should go for review before it becomes a baseline with gaps. Extraction tolerance is not a substitute for validation.
Scale creates a different set of pressures. Dozens of daily checks are low traffic, but hundreds of URLs or a higher cadence can trigger rate limits or IP blocks. Residential proxy rotation, per-domain throttling, and a managed API infrastructure layer address those network concerns. Routing also needs delivery confirmation and retries, because a detected change is not a delivered change.
Finally, a valid snapshot can still represent a temporary offer or A/B test. Keeping several older snapshots helps show when a change is reversed on the next fetch. That history supports baseline correction instead of leaving every later comparison anchored to a transient state.
Integrating the pipeline output into the workflows where pricing decisions actually get made
A reliable alert sent to an ignored inbox produces no competitive advantage. The output needs to reach the workflows for pricing response, sales enablement, product positioning, and longer-term strategy. These consumers use the same evidence differently. Sales needs to know what a change means for current deals, while a pricing team may need to decide whether to match or counter a move.
Structured diffs make those connections practical. A pricing change can trigger a downstream agent to rewrite the affected battlecard section and push it to the sales enablement platform. The same output can update a competitor’s CRM pricing field without someone typing it in. For model-driven pricing teams, it can supply current competitor prices to a model that recommends or applies a response.
Automation still needs a clear review boundary. Significant pricing actions generally warrant human review unless confidence in the pipeline is high enough for a fully automated response. Prior values, new values, and timestamps make that review fast by reducing the investigation needed. Every automated battlecard update, CRM write, or pricing-model input should retain provenance back to the specific fetch, diff, and timestamp.
Putting the pipeline together: a practical starting point for teams building this now
For teams building now, the practical sequence is to validate each stage before connecting the next. Start with specific pricing URLs, assign cadence by signal velocity, and add a lightweight URL health check. Then establish fetching and define the extraction schema. Use LLM-based extraction when the set is diverse and maintenance time is tight. Use selectors when it is small and stable. Validate the returned pricing fields before accepting a snapshot.
Next, compare the extracted fields with earlier snapshots and log each comparison with a timestamp. Treat added or removed plans as a distinct change type. Configure materiality thresholds per field, then connect webhook delivery to the intended consumers. Price changes above the chosen magnitude can alert immediately, while feature changes can be logged and batched. Keep the URL inventory and thresholds as live configuration.
Once connected, monitor fetch success rates, content validation pass rates, and diff latency. Delivery confirmation and retries need attention too. A pipeline that fails loudly gives its owners a chance to fix it. One that quietly falls apart leaves everyone reading an ever more polished work of fiction. Over months of dependable operation, the snapshots become a timestamped history of pricing moves across the competitor set. That record supports recognition of when competitors reprice and what those moves respond to, turning today’s monitoring work into evidence for future strategy.